Видео с ютуба Kv Cache Quantization

How KV Cache Speeds Up LLMs for Faster AI Models on GPUs

Объяснение TurboQuant: квантование 3-битного KV-кэша
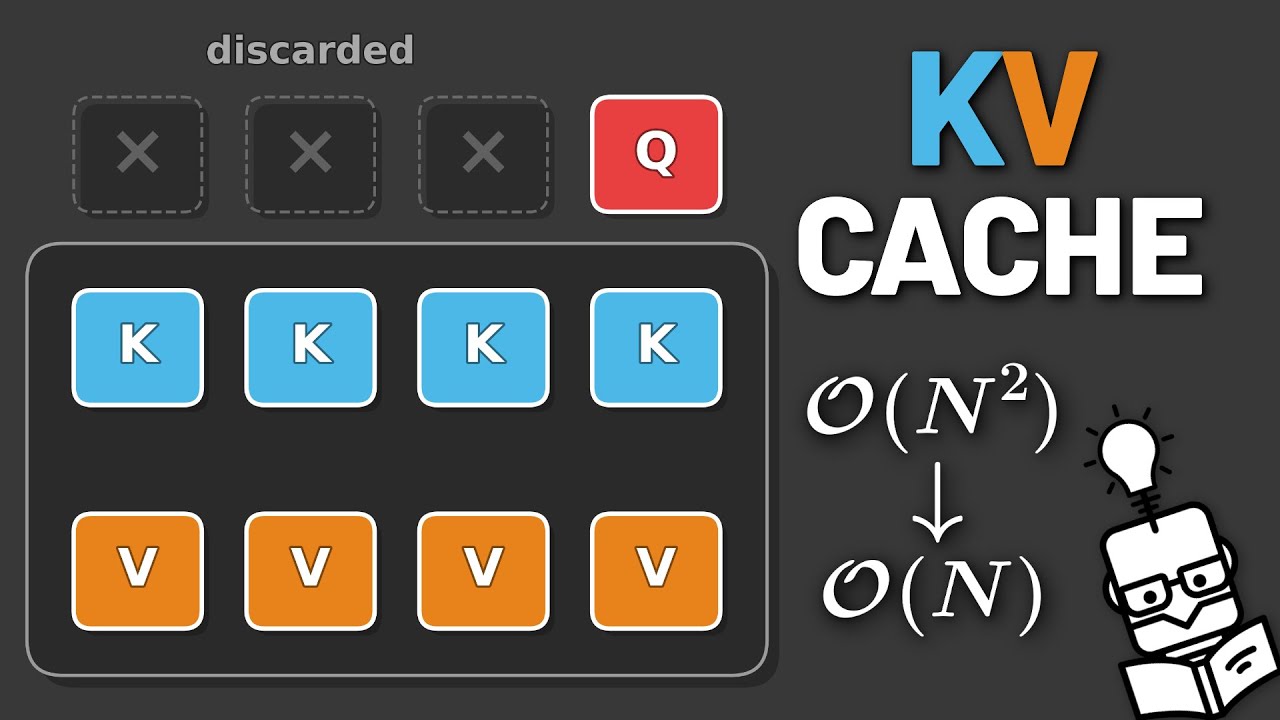
KV Cache - Explained

The KV Cache: Memory Usage in Transformers

Stop Blindly Quantizing Your KV Cache (We Tested 4 Models)

Why AI Models Run Faster on Some Chips: The KV Cache Effect

[2026/04/29 Сем 11] KV Cache. Quantization (Александр Крапухин)

KV-кэш: трюк, который ускоряет LLM
Оптимальный объем кэша ключ-значение: q4

Как использовать квантование KV-кэша для создания более длинных текстов в LLM

Inference Engineering Lecture 3: KV Cache, Prefill & Decode, GPU Architecture and TurboQuant

2406.03482 - QJL: 1-Bit Quantized JL Transform for KV Cache Quantization with Zero Overhead

Run LLMs Locally: KV Cache, Quantization and GGUF Explained

OScaR: 2-Bit KV Cache Quantization for LLMs

KV Cache f16 vs q8 vs q4: Tested at Every Depth

Why LLM Inference Memory Grows With Context | KV Cache Explained Visually

LLM Inference and KV Cache Explained: Memory, Context, Routing and Quantization
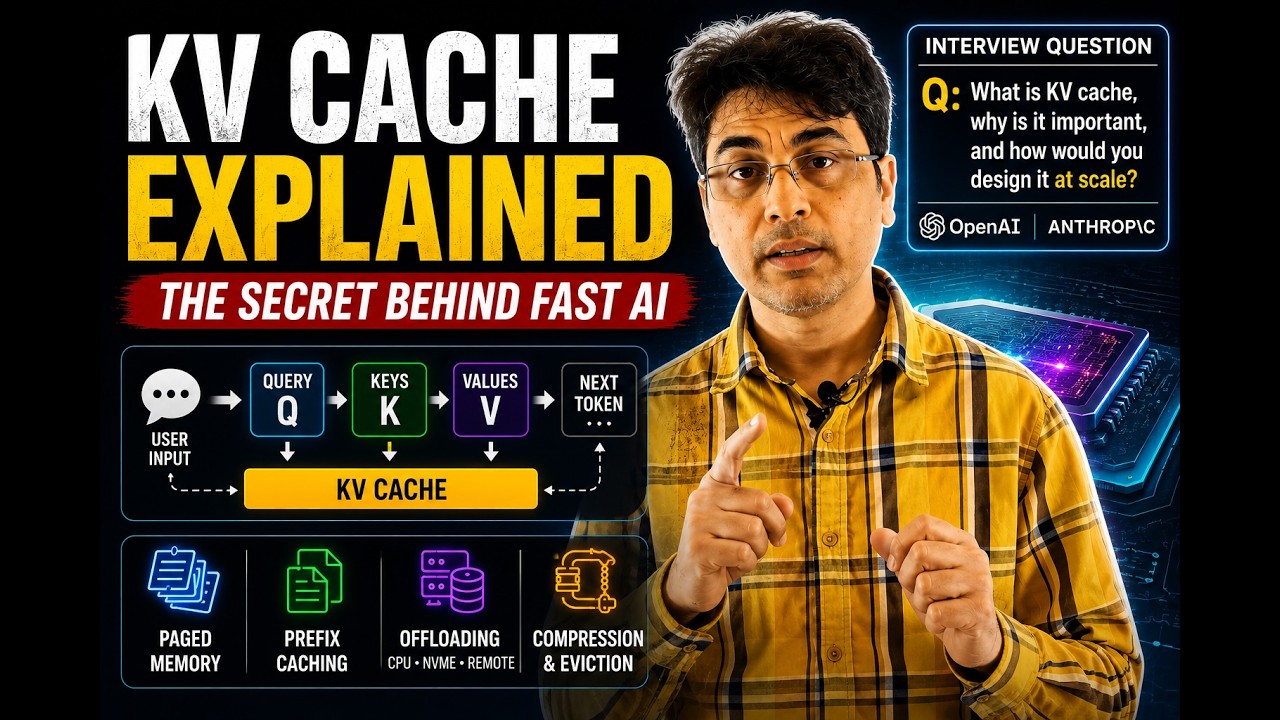
KV Cache Explained | LLM Inference System Design and GPU Memory